SFT vs RLHF vs DPO
SFT - Supervised Fine Tuning
Instruct model how to respond.
rlhf - Reinforcement Learning w Human Feedback
Rank answers from best to worse and model learns to adhere to human taste.
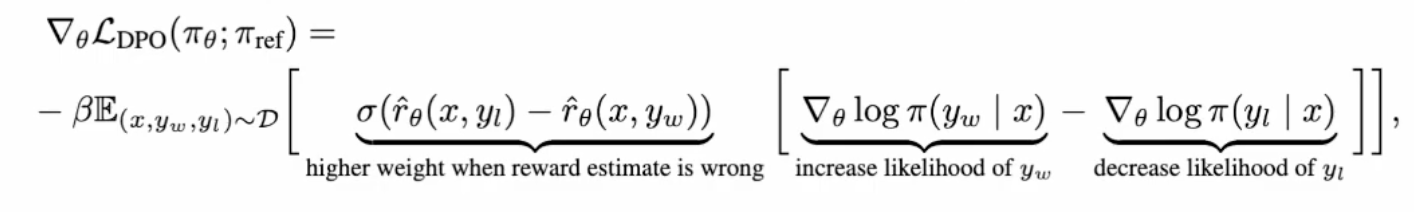
dpo - Direct Policy optimization
- Using a special cross-entropy - compare the logits (the raw output scores before probabilities) from two models:
- Trained model: feed both the preferred response and the dispreferred response, get the logits for both.
- Reference model (frozen older version of LLM, often can be SFT model we started with): feed both the preferred response and the dispreferred response, get the logits for both.
- Calculate cross-entropy loss function with above logits
- https://www.youtube.com/watch?v=aB7ddsbhhaU
- https://arxiv.org/pdf/2203.02155