Blog
Notes on building, evaluating, and shipping AI agents.
SFT vs RLHF vs DPO
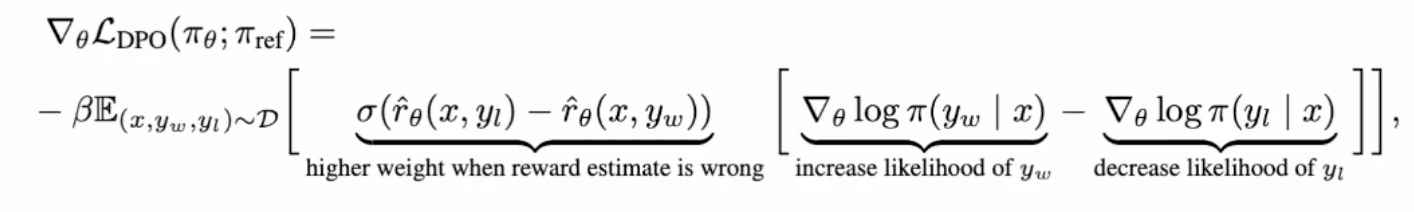
SFT vs RLHF vs DPO: instruction tuning, ranking answers to human taste, and DPO's cross-entropy over trained vs frozen reference model logits.
Deploying AI Agents: Local vs Prod - like launching a rocket
What to fix locally (goldens, judge calibration) vs what only matters in prod (tracing, timeouts, evals), plus the top 3 mistakes ranked.
Anthropic Outages: What Fails and Why
Anthropic ships faster than its infra matures - near-daily outages. Which components fail, why AI systems pick availability, and the fixes.

Headroom: Local Context Compression for AI Agents
Headroom is a local context-compression layer between agent and LLM: 60-95% on JSON, 15-20% for coding agents, without breaking provider cache.

Sanitizing AI Agents: MCP RBAC & the Lethal Trifecta
Sanitizing agent tools: MCP RBAC, separating high-privilege tools from external context, and never combining the lethal trifecta.
Why My Chrome Extension Got 11 Uninstalls a Day
Real users said my LinkedIn Post Formatter extension 'doesn't work' - ~11 uninstalls a day. What was actually broken and the stats after the fix.

LLM Gateway Caching & CAP Tradeoffs
LLM gateway caching and CAP: cache-aside, write-through and semantic caching on embeddings - plus the consistency tradeoffs each one buys.
AI Infra Queues: Token-Aware Buffering for GPUs
Queueing for AI infra: token-aware buffering, session priority, concurrency control and MCP route shielding to stop GPU OOM and cascades.
LLM Parameters Cheat Sheet: 7 Model APIs Compared
LLM parameter cheat sheet across gpt-4o, gpt-5.2, claude, gemini, mistral, cohere and vLLM - which names differ from the OpenAI spec.

AI Load Balancing: L4 vs L7 and KV Cache Hashing
AI load balancing: what L7 decodes that L4 can't (MCP, tool auth, guardrails), consistent hashing for sticky KV cache, and GPU health checks.
AI Gateway Failover & Rate Limiting
AI gateway system design: one LLM backend goes 10x slower - how queues, backpressure, load shedding and rate limits stop the cascade.
LLM Jailbreaks & Prompt Injection: 10 Models Scored
LLM security field notes: grandma/base64/suffix jailbreaks, prompt injection via web pages and Google Docs, and how 10 models scored on each.
How to Eval Your AI Agent: Goldens and LLM-as-Judge
Eval your agent before you tune it: frozen goldens, LLM-as-judge, and how to decide model, MCP servers, sampling params and quality thresholds.